Everything you need to know about must know failure modes in distributed.
[ad_1]What does it mean for a distributed system to be up?
On a single machine, the answer is straightforward, since a program is either running or it has crashed, and the line between the two is usually obvious from a stack trace.
Distributed systems are not so simple. Every server can report healthy while users are seeing errors, the whole system can be technically working but stuck in a state it cannot recover from on its own, and it can quietly serve wrong data while every dashboard glows green.
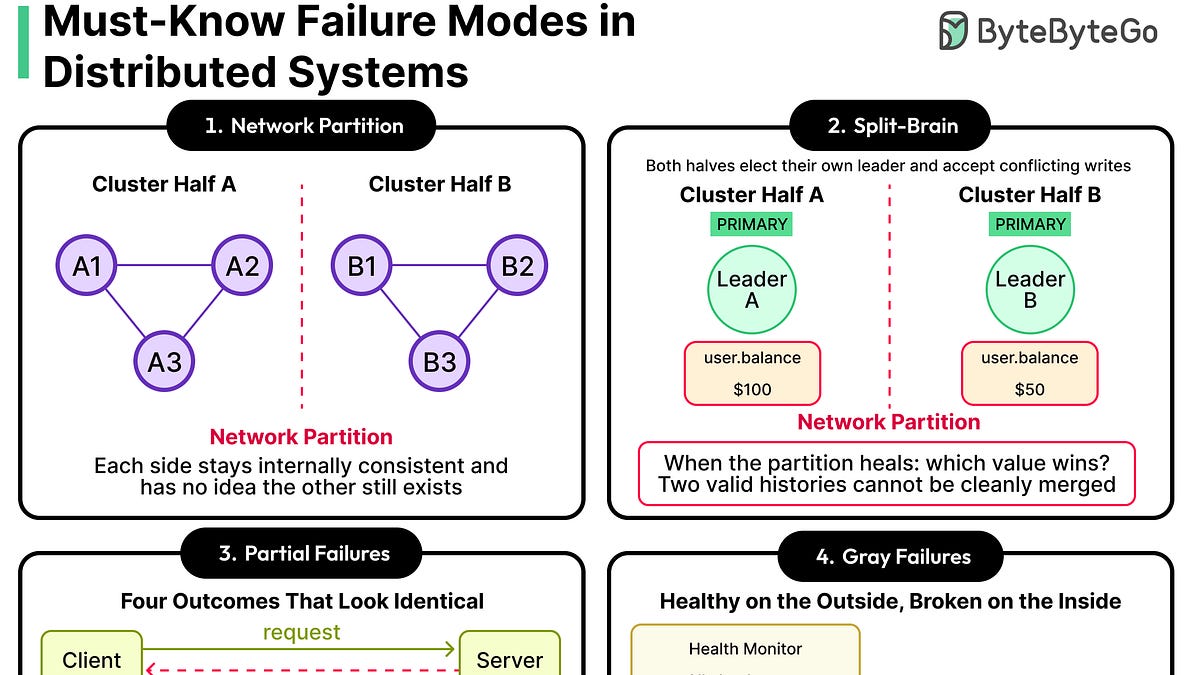
None of these may be because of bugs in the conventional sense. They are recurring failure patterns that have been showing up across systems for decades, with names, mechanisms, and standard ways of defending against them.
In this article, we will look at the most significant failure mode patterns in distributed systems and the standard approaches to deal with each of them.
[ad_2]
Source link
More on must know failure modes in distributed
Stay tuned for updates on must know failure modes in distributed as the story develops. Related: The Organizational Playbook for Engineering Transformation at Scale.
Frequently Asked Questions
The most significant recurring failure-mode patterns in distributed systems, with their mechanisms and standard defenses.
Every server can report healthy while users see errors; the system can get stuck unrecoverably or quietly serve wrong data while dashboards glow green.
Not in the conventional sense — they're recurring patterns seen across systems for decades, with names, mechanisms, and standard ways of defending against them.
It's not straightforward — on a single machine a program is either running or crashed, but distributed "up" is much murkier.