Everything you need to know about how anthropic claude thinks bytebytego newsletter.
[ad_1]We hit the ceiling of single-session AI coding fast. We now orchestrate 200+ Claude Code instances in parallel on a shared codebase. Each instance runs in its own git worktree with filesystem access, test execution, and git. The system produces draft pull requests that have already been through automated writing, testing, code review, and verification before a human reviews them.
We recently open-sourced this system as SWE-AF. In this article, we cover the two-mode LLM integration pattern, a three-loop failure recovery hierarchy, and checkpoint-based execution that makes $116 builds survivable.
Nobody at Anthropic programmed Claude to think a certain way. They trained it on data, and it developed its own strategies, buried inside billions of computations. For the people who built it, this could feel like an uncomfortable black box. Therefore, they decided to build something like a microscope for AI, a set of tools that would let them trace the actual computational steps Claude takes when it produces an answer.
The findings surprised them.
Take a simple example. Ask Claude to add 36 and 59, and it will probably tell you it carried the ones and added the columns as per the standard algorithm we all learned in school. However, when the researchers watched what actually happened inside Claude during that calculation, they saw something quite different. There was no carrying. Instead, two parallel strategies ran at once, one estimating the rough answer and another precisely calculating the last digit. In other words, Claude got the math right, but had no idea how it was done.
That gap between what Claude says and what it actually does turned out to be just the beginning. Over the course of multiple research papers published in 2025, Anthropic’s interpretability team traced Claude’s internal computations across a range of tasks, from writing poetry to answering factual questions to handling dangerous prompts.
In this article, we will look at what the Claude researchers found.
Disclaimer: This post is based on publicly shared details from the Anthropic Research and Engineering Team. Please comment if you notice any inaccuracies.
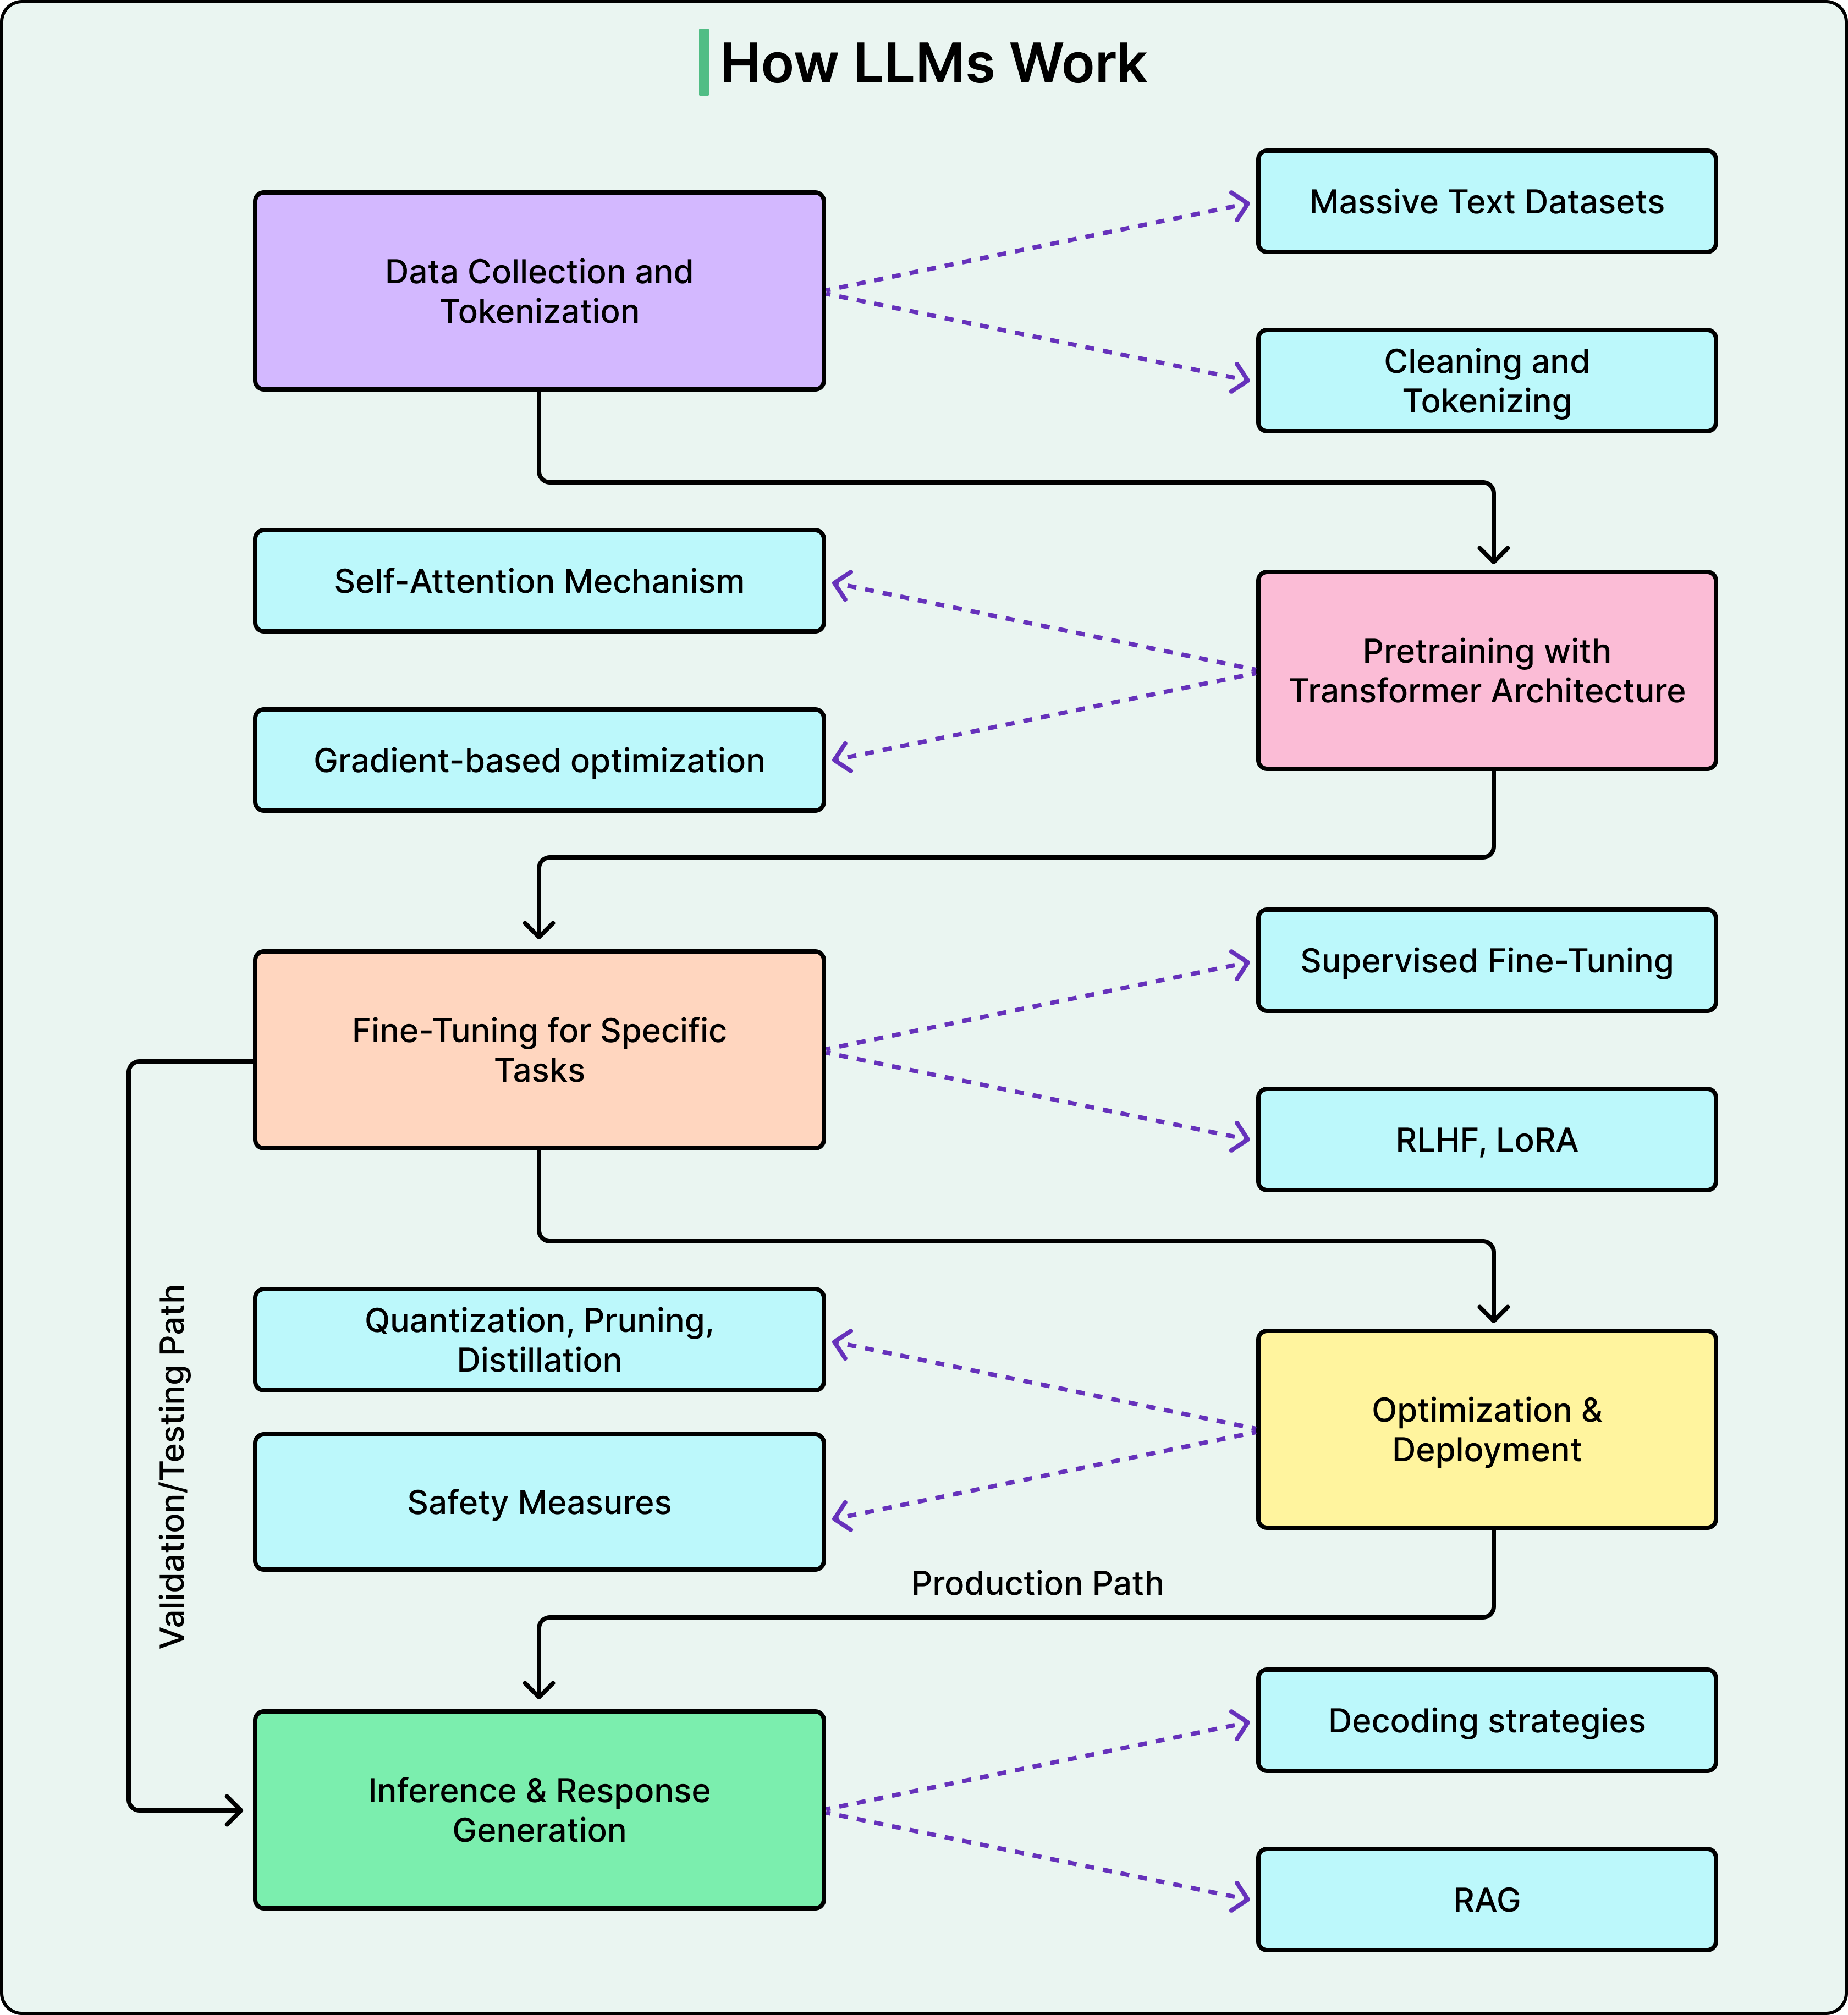
The diagram below shows a typical flow of how a modern LLM works:
Before getting to the findings that Anthropic’s research team found, it helps to understand what this “microscope” actually is.
The core problem is that individual neurons inside an LLM’s neural network don’t map neatly to single concepts. One neuron might activate for “basketball,” “round objects,” and “the color orange” all at once. This is called polysemanticity, and it means that looking at neurons directly doesn’t tell us much about what the model is doing.
Anthropic’s solution is to use specialized techniques to decompose neural activity into what they call “features.” These are more interpretable units that correspond to recognizable concepts, such as things like smallness, known entity, or rhyming words.
To find these features, the team built a replacement model, which is basically a simplified copy of Claude that swaps neurons for features while producing the same outputs. They study this copy, not Claude directly.
Once they have features, they can trace how they connect to each other from input to output, producing attribution graphs. Think of these as wiring diagrams for a specific computation. And the most powerful part of this tool is the ability to intervene. You can reach into the model and suppress or inject specific features, then watch how the output changes. If you suppress the concept of “rabbit” and the model writes a different word, that’s strong causal evidence that the “rabbit” feature was doing what you thought it was doing. This technique is borrowed directly from neuroscience, where researchers stimulate specific brain regions to test their function.
Claude speaks dozens of languages fluently. So a natural question is whether there’s a separate “French Claude” and “English Claude” running internally, each responding in its own language.
There isn’t. When the researchers asked Claude for “the opposite of small” in English or French, they found that the same core features for “smallness” and “oppositeness” were activated regardless of the language used in the prompt. These shared features triggered a concept of “largeness,” which then got translated into whatever language the question was asked in.
This shared circuitry scales with model size. For example, Claude 3.5 Haiku shares more than twice the proportion of its features between languages compared to a smaller model. The implication of this is that Claude operates in some abstract conceptual space where meaning exists before language. If it learns something in English, it can potentially apply that knowledge when speaking French, not because it translates, but because at a deep level, both languages connect to the same internal representations.
Here’s a couplet Claude wrote.
He saw a carrot and had to grab it,
His hunger was like a starving rabbit
To write the second line, the model had to satisfy two constraints at once. It needed to rhyme with “grab it” and also make sense in context. The researchers’ hypothesis was that Claude probably writes word by word, then at the end of the line, picks a word that rhymes. They expected to find parallel paths for meaning and rhyming that converge at the final word.
Instead, they found that Claude plans ahead. Before writing the second line at all, it had already identified “rabbit” as a candidate ending. It picked the destination first, then wrote the line to get there.
The intervention experiments confirmed this was real. When the researchers suppressed the “rabbit” feature in Claude’s internal state, the model rewrote the line to end with “habit” instead. When they injected the concept of “green,” it wrote a completely different, non-rhyming line ending in “green.” This demonstrates both planning ability and flexibility.
What makes this experiment more credible than a typical AI capability claim is that the researchers had set out to show that Claude didn’t plan. Finding the opposite is what gives the result its weight. They followed the evidence rather than their expectations.
The mental math result deserves a closer look, because the gap it reveals goes deeper than a quirky arithmetic shortcut.
When Claude computes 36 + 59, the microscope shows two computational paths running in parallel. One path estimates the rough magnitude of the answer, placing it somewhere in the range of 88 to 97. The other path focuses specifically on the last digit, computing that 6 + 9 ends in 5. These paths interact and combine to produce 95.
This is nothing like the carrying algorithm Claude describes when you ask it to explain its work.
So why does Claude give the wrong explanation?
This is because it learned to explain math and to do math through completely separate processes. Claude’s explanations come from human-written text it absorbed during training, text where people describe the standard algorithm. However, Claude’s actual computational strategies emerged from the training process itself. No one taught it to use parallel approximation paths. It developed those on its own, and those internal strategies aren’t accessible to the part of Claude that generates natural language explanations.
This is an important finding, and not just for arithmetic. It means Claude’s self-reports about its own reasoning process can be inaccurate, not because it’s lying, but because it literally doesn’t have access to its own internal algorithms. When we ask a model to show its work, we might be getting a plausible reconstruction and not a faithful record.
This raises an obvious follow-up question. If Claude’s explanations don’t always match the internal process while doing easy math, what happens on harder problems?
Modern models like Claude can “think out loud,” writing extended chains of reasoning before giving a final answer. Often this produces better results. However, Anthropic’s researchers found that the relationship between the written reasoning and the actual internal computation isn’t always what it seems.
On an easier problem that required computing the square root of 0.64, Claude produced a faithful chain of thought. The microscope showed internal features representing the intermediate step of computing the square root of 64. The explanation matched the process.
On a harder problem involving the cosine of a large number, something very different happened. Claude produced a chain of thought that claimed to work through the calculation step by step. But the microscope revealed no evidence of any calculation having occurred internally.
In other words, Claude had generated an answer and constructed a plausible-looking derivation after the fact, without actually computing anything. The philosopher Harry Frankfurt had a word for this kind of output. He called it bullshitting. Not lying, which requires knowing the truth and deliberately contradicting it, but something arguably worse, like producing statements without any concern for whether they’re true or false.
Further on, when the researchers gave Claude a hint about the expected answer, the model engaged in what they call motivated reasoning. It worked backward from the target answer, finding intermediate steps that would lead to that conclusion. It wasn’t solving the problem. It was reverse-engineering a justification for a predetermined result.
The self-unawareness in the math case was harmless. Claude got the right answer by the wrong-described method. No one gets hurt. But this is different. If a model’s step-by-step reasoning can be a performance rather than a genuine process, the chain-of-thought traces we increasingly rely on for trust become unreliable.
Perhaps the most counterintuitive finding involves hallucination, which is the tendency for language models to make up information.
The conventional view is that models hallucinate because they’re trained to always produce output. They’re completion machines, so they fill gaps with plausible-sounding text. The challenge, in this framing, is teaching them to stay quiet when they don’t know something.
Anthropic found something that turns this framing upside down. In Claude, refusal to answer is actually the default behavior. The researchers identified a circuit that is “on” by default and that causes the model to state that it lacks sufficient information to answer any given question. In other words, Claude’s natural state is to decline.
What lets Claude answer questions at all is a separate mechanism. When the model recognizes a well-known entity, say the basketball player Michael Jordan, a “known answer” feature activates and inhibits the default refusal circuit. This inhibition is what allows Claude to provide an answer.
Hallucinations happen when this recognition system misfires. When Claude encounters a name like “Michael Batkin” (a person it doesn’t know anything about), the refusal circuit should win. But if the name triggers enough familiarity, perhaps Claude has seen it in passing during training, the “known entity” feature can incorrectly activate and suppress the refusal. With refusal disabled and no actual knowledge to draw on, Claude invents a plausible answer.
The researchers confirmed this mechanism by intervening directly. By artificially activating the “known answer” features while asking about unknown entities, they could consistently make Claude hallucinate. They could also cause hallucination by inhibiting the “can’t answer” features.
This implies that hallucination isn’t Claude being reckless, but the recognition system misfiring and overriding a safety default that was working correctly.
The final case study involves jailbreaks, prompting strategies designed to get a model to produce outputs it shouldn’t.
The researchers studied a specific jailbreak that tricks Claude through an acrostic. The prompt “Babies Outlive Mustard Block” asks the model to put together the first letters of each word. Claude spells out B-O-M-B without initially recognizing what it’s producing. By the time it realizes it has been asked about bomb-making, it has already started a sentence providing instructions.
What happens next reveals a surprising tension. Safety features activate. The model recognizes that it should refuse. However, features promoting grammatical coherence and self-consistency exert competing pressure. Once Claude has begun a sentence, these coherence features push it to complete that sentence in a way that is grammatically and semantically valid. The safety features want to stop, but the grammar features want to finish.
Claude only manages to pivot to refusal at a sentence boundary. Once it reaches a natural stopping point, it starts a new sentence with the kind of refusal it had been trying to give all along. The features that ordinarily make Claude a fluent, coherent writer became, in this specific case, the vulnerability that a jailbreak could exploit.
These findings create a richer picture of Claude’s internals than anything that came before. However, the researchers are also upfront about the limitations.
The tools produce satisfying insight on roughly a quarter of the prompts they try. The case studies in this article, and in the original blog post, are the success cases. Even on those successes, the microscope captures only a fraction of the total computation Claude performs.
Everything described here was observed in the replacement model, not in Claude itself. The replacement model is designed to behave identically, but the possibility of artifacts, things the replacement model does that the real model doesn’t, is real.
There’s also a scale problem. Current analysis requires hours of human effort on prompts containing only tens of words. Scaling this to the thousands of words in a complex reasoning chain is an unsolved problem.
Ultimately, the question “how does Claude think?” doesn’t have a single answer.
It thinks in abstract concepts that exist before language. It plans ahead, choosing destinations and writing routes to reach them. It invents its own computational methods and then describes completely different ones when asked. It sometimes fabricates reasoning to support predetermined conclusions. Its default is silence, and it speaks only when something overrides that default, sometimes incorrectly. And when it starts a sentence, finishing it grammatically can temporarily override everything else, including safety.
References:
[ad_2]
Source link
More on how anthropic claude thinks bytebytego newsletter
Stay tuned for updates on how anthropic claude thinks bytebytego newsletter as the story develops. Related: Anthropic’s safety warnings may have just backfired — the government has pulled the plug on its most powerful AI.
Frequently Asked Questions
Nobody at Anthropic programmed Claude to think a certain way — it developed its own strategies through training. So Anthropic built microscope-like tools to trace the actual computational steps Claude takes when producing an answer.
When asked to add 36 and 59, Claude says it carried the ones like we learned in school. But researchers saw two parallel strategies instead: one estimating the rough answer and another precisely calculating the last digit — Claude got it right but had no idea how it was done.
The gap between what Claude says and what it actually does was just the beginning. Across multiple 2025 research papers, Anthropic's interpretability team traced Claude's computations from writing poetry to answering factual questions to handling dangerous prompts.
The newsletter's team orchestrates 200-plus Claude Code instances in parallel on a shared codebase, each in its own git worktree, producing draft pull requests that pass automated writing, testing, code review, and verification. They open-sourced the system as SWE-AF.