Everything you need to know about deepseek v4 preview launches with open.
[ad_1]Chinese AI company DeepSeek caused quite a stir last year as it climbed to the top of the App Store charts and beat out incumbents like ChatGPT. That was over a year ago and now the company has launched a preview of its latest and much more capable model dubbed DeepSeek-V4.
If you have a DeepSeek account, you can try out the new model here: chat.deepseek.com/. There are two versions available, Expert and Instant. Expert is a massive 1.6 trillion parameter model, Instant is a more reasonable (but still huge) 284 billion parameter model.
DeepSeek-V4 Pro and Flash modelsAnd here’s the most interesting part – this is an open-weights model, meaning that you can download it from Hugging Face and run it on your own hardware at home. Well, you could theoretically – you would need some serious hardware to actually run these models.
Now, the Expert (Pro) model has 49 billion active parameters and Instant (Flash) has only 13 billion active parameters – these are the parameters that actually need to fit in VRAM. However, shuffling parameters between VRAM and system memory slows down token generation. The good thing about open-weight models is that the community can create quantized and distilled models that can actually run on consumer-level hardware.
Anyway, the company says that DeepSeek-V4-Flash, the model that powers Instant mode, has reasoning capabilities close to that of V4-Pro and performs just as well on simple agentic tasks. Both models have a 1 million token context window.
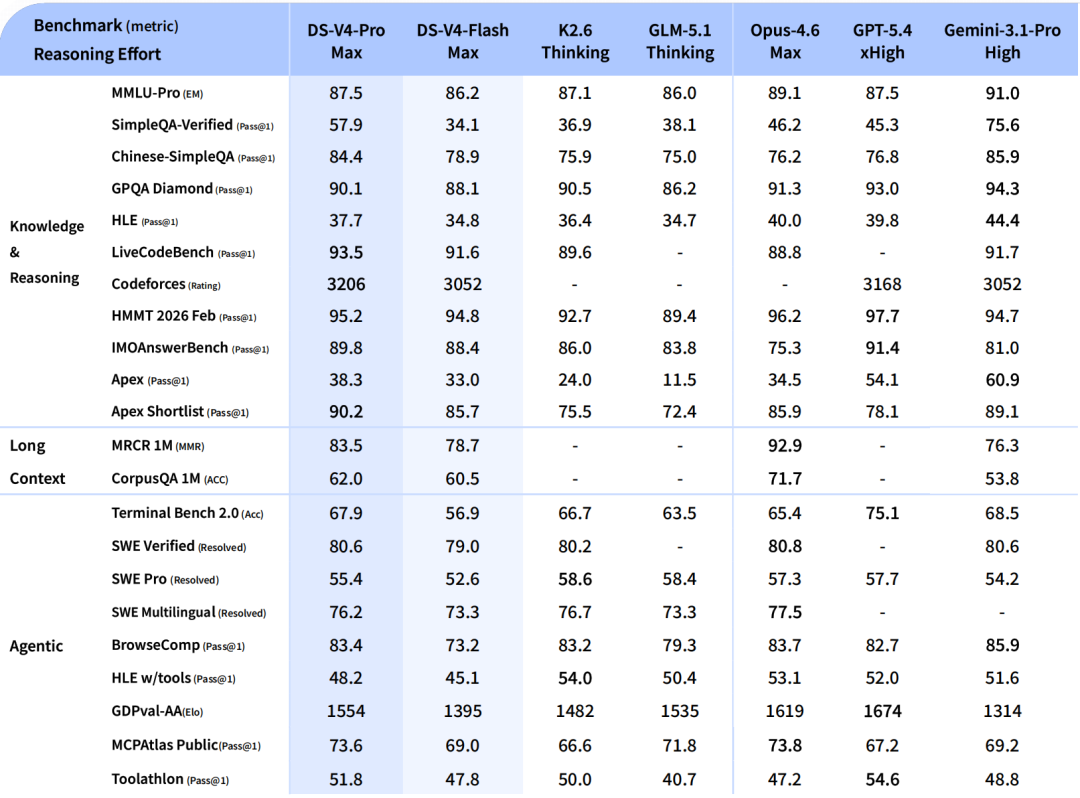
DeepSeek-V4-Pro, which is behind the Expert mode, has the best reasoning skills for math, STEM and coding tasks among open-weight models and rivals the performance of closed-source models, according to DeepSeek testing. V4-Pro also beats most AI models in terms of world knowledge, only losing to Google’s Gemini-3.1-Pro, says the company.
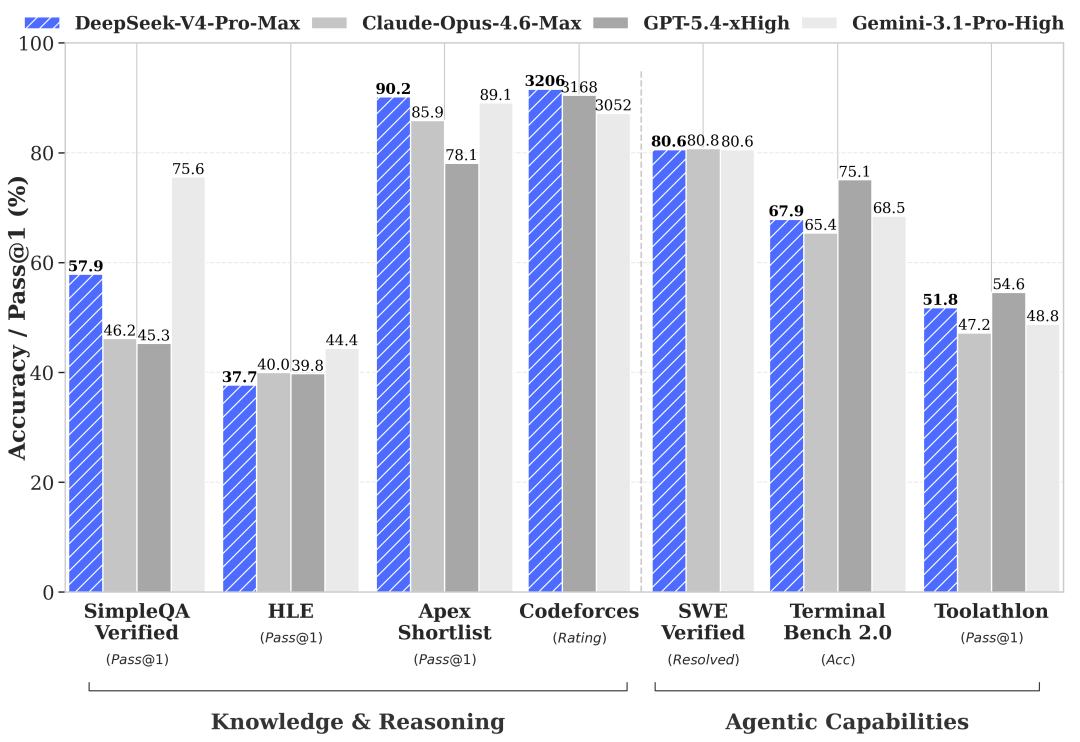 DeepSeek-V4-Pro versus its major competitors
DeepSeek-V4 can be used with popular tools like Claude Code, OpenClaw and OpenCode. If you can’t run the model at home, you can use the company’s API. Here’s the pricing:
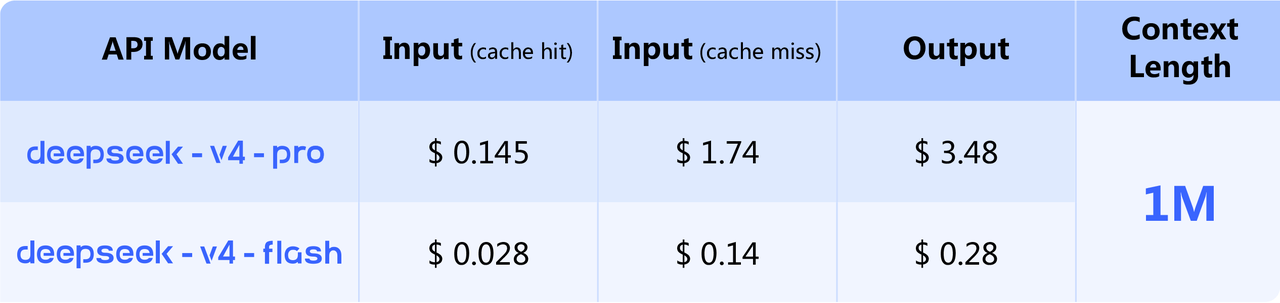 DeepSeek-V4 Pro and Flash API pricing
[ad_2]
Source link
More on deepseek v4 preview launches with open
Stay tuned for updates on deepseek v4 preview launches with open as the story develops. Related: Real-time LLM Inference on Standard GPUs (3,000 tokens/s per request).
Deepseek v4 preview launches with open: Key Details Explained
DeepSeek-V4 Preview launches with open weights and API access — let’s break down what actually matters here. This one stands out because it touches the things buyers care about most: performance, features, and value for money. If you’re comparing options right now, it’s worth keeping on your shortlist.
Looking at the bigger picture, this fits into a wider trend where brands compete harder with every release cycle. Expect more details to surface as things develop, including confirmed specifications and pricing from official sources.
Should You Keep Following This?
If you follow mobile tech closely, the answer is yes. Developments like this could influence your next purchase decision, so it’s worth tracking. Bookmark this page — we’ll keep the coverage fresh as the story evolves.
Frequently Asked Questions
There are two versions: Expert, a massive 1.6 trillion parameter model, and Instant, a smaller 284 billion parameter model. You can try them at chat.deepseek.com with a DeepSeek account.
It is an open-weights model downloadable from Hugging Face, though running it at home would need serious hardware. The community can create quantized and distilled versions that run on consumer hardware.
According to DeepSeek's testing, V4-Pro has the best reasoning for math, STEM, and coding among open-weight models, rivals closed-source models, and beats most models on world knowledge, losing only to Google's Gemini-3.1-Pro.
Both models have a 1 million token context window, and the company says V4-Flash performs just as well as V4-Pro on simple agentic tasks.