Everything you need to know about an open weights chinese model just.
[ad_1]By Rohana Rezel
I’m running the ongoing AI Coding Contest where I pit major language models against each other in real-time programming tasks with objective scoring. Day 12 was the Word Gem Puzzle. Ten models entered. The results were not what most people would have predicted.
Kimi K2.6, an open-weights model from Chinese startup Moonshot AI, won the challenge outright: 22 match points, 7-1-0. MiMo V2-Pro from Xiaomi came second. GPT-5.5 was third. Claude Opus 4.7 finished fifth. Every model from the Western frontier labs landed below the top two.
The challenge
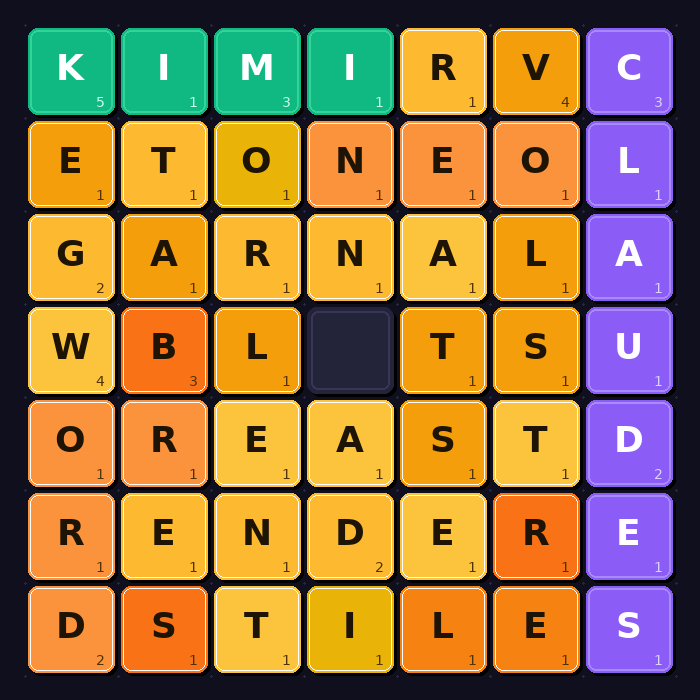
The Word Gem Puzzle is a sliding-tile letter puzzle. The board is a rectangular grid (10×10, 15×15, 20×20, 25×25, or 30×30) filled with letter tiles and one blank space. Bots can slide any adjacent tile into the blank and at any point claim valid English words formed in straight horizontal or vertical lines. Diagonals don’t count. Backwards doesn’t count.
The scoring rewards longer words and punishes short ones. Words under seven letters cost points: a five-letter word loses you one point, a three-letter word costs three. Seven letters or more score their length minus six, so an eight-letter word is worth two points. The same word can only be claimed once; if another bot gets there first, you get nothing. Each pair of models played five rounds, one per grid size, with a ten-second wall-clock limit per round.
The grids are seeded with real dictionary words in a crossword-style layout, then the remaining cells are filled with letters weighted by Scrabble tile frequencies, and finally the blank is scrambled, more aggressively on larger boards. On a 10×10, many seed words survive intact. On a 30×30, almost none do. That turns out to matter a lot.
The code produced by Nvidia’s Nemotron Super 3 contained a syntax error, so it never connected to the game server. Nine models actually competed.
| Rank | Model | Match Points | Record |
|---|---|---|---|
| 1 | Kimi K2.6 | 22 | 7-1-0 |
| 2 | MiMo V2-Pro | 20 | 6-2-0 |
| 3 | ChatGPT GPT-5.5 | 16 | 5-1-2 |
| 4 | GLM 5.1 | 15 | 5-0-3 |
| 5 | Claude Opus 4.7 | 12 | 4-0-4 |
| 6 | Gemini Pro 3.1 | 9 | 3-0-5 |
| 7 | Grok Expert 4.2 | 9 | 3-0-5 |
| 8 | DeepSeek V4 | 3 | 1-0-7 |
| 9 | Muse Spark | 0 | 0-0-8 |
Kimi K2.6 is open-weights, publicly available from Moonshot AI, a Chinese startup founded in 2023. MiMo V2-Pro is currently API-only; the tweet linked here is Xiaomi confirming that weights for their newer V2.5 Pro model are dropping soon. The models from Anthropic, OpenAI, Google, and xAI placed third through seventh. GLM 5.1, from Chinese lab Zhipu AI, placed fourth. DeepSeek finished eighth. This isn’t a clean China-beats-West story; it’s two specific models that won.
What I saw
The move logs tell the story. Kimi won by sliding aggressively. Its approach was greedy: score each possible move by what new positive-value words it unlocks, execute the best one, repeat. When no move unlocked a positive word, it fell back to the first legal direction alphabetically. This caused some inefficient edge-oscillation, a 2-cycle pattern where the bot bounced the blank back and forth without progress. On smaller grids where seed words were still largely intact, that hurt. On the 30×30 grids, where the scramble had broken up nearly everything and reconstruction was the only path to points, the sheer slide volume eventually paid off. Kimi’s cumulative score of 77 was the highest in the tournament.
MiMo’s sliding code exists in the repo, but its “best value greater than zero” threshold never triggered, so in practice it never slid once. It went straight to scanning the initial grid for words of seven letters or more and blasted all its claims in a single TCP packet. Brittle strategy: entirely dependent on the scramble leaving intact seed words. On grids where words survived, MiMo cleaned up fast. On grids where they didn’t, it scored nothing. Final tally: 43 cumulative points, second place.
Claude also didn’t slide. The move logs show it holding up well on 25×25 boards where scramble density was still manageable, then falling apart on 30×30 where actual tile movement was needed. Not sliding is a real limitation in a puzzle built around sliding.
GPT-5.5 was more conservative, roughly 120 slides per round with a cap to avoid thrashing, and showed the strongest numbers on 15×15 and 30×30 grids. Grok never slid either, yet scored reasonably on the larger boards. GLM was the most aggressive slider in the whole tournament, over 800,000 total slides, but stalled badly whenever it ran out of positive moves.
DeepSeek sent malformed data every round. Zero useful output. At least it didn’t make things worse by playing.
Muse made things worse by playing.
The scoring penalizes short words: three-letter words cost three points, four-letter words cost two, five-letter words cost one. The intent is to stop bots from carpet-bombing the board with “the” and “and” and “it.” Every serious competitor filtered their dictionary to words of seven letters or more. Muse claimed everything. Every word it could find, regardless of length, fired off as a claim. On a 30×30 grid with hundreds of short valid words visible at any moment, Muse found them all and claimed every one.
Its cumulative score was −15,309. It lost all eight matches and won zero rounds. There is a version of Muse that simply connected to the server and did nothing, and that version would have scored zero, a 15,309-point improvement. The gap between Muse and eighth place was larger than the gap between eighth and first.
DeepSeek’s malformed output tells you something about how it handles novel protocol specs under time pressure. Muse’s spiral tells you something different: it saw valid words and claimed them, with no apparent model of what “valid” meant given the scoring rules. It read the task partially and executed that partial reading in full. Worth noting for anyone deploying these models on structured tasks with penalties.
What surprised me
I design these challenges, so I have a reasonable sense of what they test. What I didn’t fully anticipate was how starkly the 30×30 grids would separate the field. On smaller boards, the difference between a static scanner and an active slider was modest. At full scale, models that could only find what was already there ran out of road. Kimi’s greedy loop, flawed as it was, kept producing output when the static scanners had nothing left to claim.
The other thing worth noting: MiMo and Kimi finished two points apart despite doing almost opposite things. Two different theories of the same puzzle, nearly identical results. That means the gap between first and second was partly seed variance, not just capability difference.
The bigger picture
One fair counterargument: this scoring system rewards aggressive word claiming, and heavily safety-tuned models may be more conservative about that kind of carpet-bombing. If so, the results reflect a mismatch between task design and aligned model behaviour, not raw capability. It’s a reasonable objection. It doesn’t change the outcome.
One challenge doesn’t overturn general benchmarks. This puzzle tests real-time decision-making and whether a model can write clean functional code that connects to a TCP server and plays a novel game correctly. It doesn’t test long-context reasoning or code generation from a spec.
But I’ve been running these challenges long enough to notice what’s changing. A year ago, the assumption was that the Western frontier labs had a capability lead open-weights couldn’t close. Kimi K2.6 now scores 54 on the Artificial Analysis Intelligence Index. GPT-5.5 scores 60, Claude 57. That’s not parity, but it’s close, and it’s coming from a model anyone can download.
When models within a few index points of the frontier are also freely available to run locally, that’s a different competitive situation than the one that existed a year ago. This challenge is one data point in that shift. The gap is small enough now that it shows up in results like this one.
Rohana Rezel runs the AI Coding Contest and is a technologist, researcher, and community leader based in Vancouver, BC.

[ad_2]
Source link
More on an open weights chinese model just
Stay tuned for updates on an open weights chinese model just as the story develops. Related: GLM-5.2 vs Claude Opus | Tech Stackups.
An open weights chinese model just: Key Details Explained
An open-weights Chinese model just beat Claude, GPT-5.5, and Gemini in a programming challenge — let’s break down what actually matters here. This one stands out because it touches the things buyers care about most: performance, features, and value for money. If you’re comparing options right now, it’s worth keeping on your shortlist.
Looking at the bigger picture, this fits into a wider trend where brands compete harder with every release cycle. Expect more details to surface as things develop, including confirmed specifications and pricing from official sources.
Should You Keep Following This?
If you follow mobile tech closely, the answer is yes. Developments like this could influence your next purchase decision, so it’s worth tracking. Bookmark this page — we’ll keep the coverage fresh as the story evolves.
Frequently Asked Questions
Kimi K2.6, an open-weights model from Chinese startup Moonshot AI, won outright with 22 match points and a 7-1-0 record.
MiMo V2-Pro from Xiaomi came second, GPT-5.5 was third, Claude Opus 4.7 finished fifth, and every model from the Western frontier labs landed below the top two.
It is a sliding-tile letter puzzle on grids from 10×10 to 30×30, where bots slide tiles into a blank and claim valid English words in straight horizontal or vertical lines, with longer words scoring more and short words costing points.
Its generated code contained a syntax error, so it never connected to the game server.